The estimated reading time for this article is about 3 minutes.
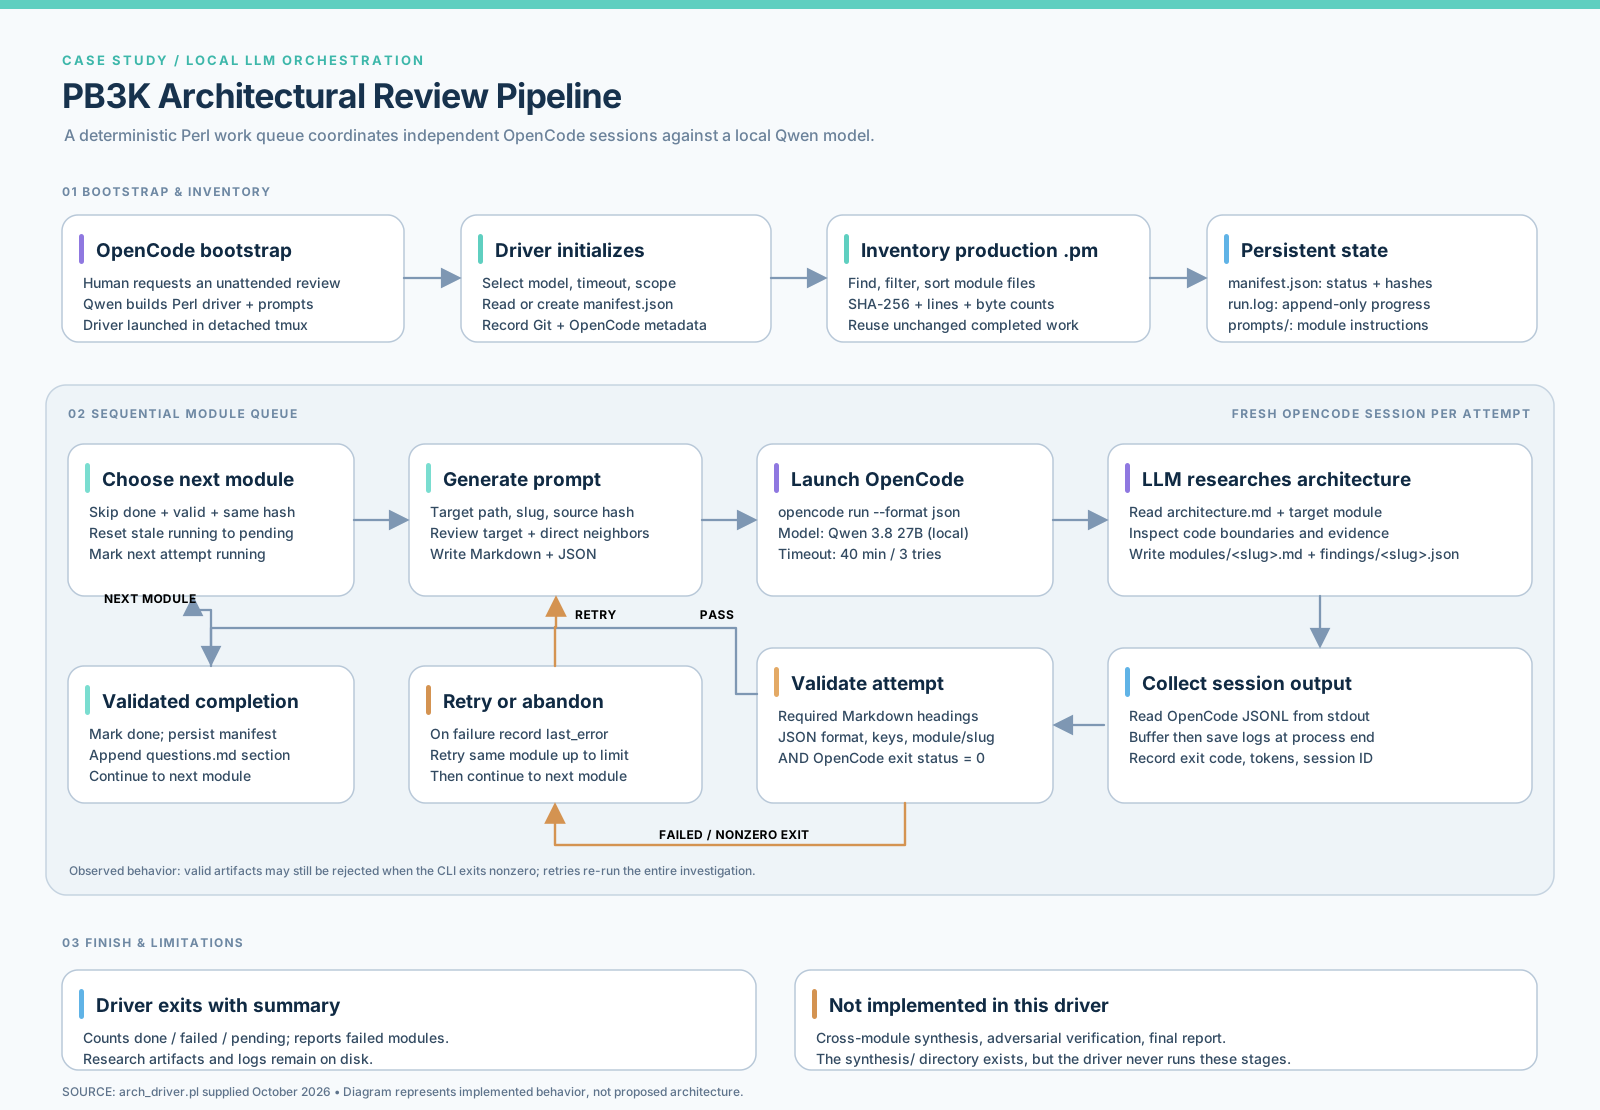
Whelp, that certainly is a flowchart. Let's stick a pin in that for a bit.
I have a modest unified memory archive AMD Strix Halo machine with 64GB of RAM running Ubuntu with ROCm. I bought this in early September 2026 and with Amazon points, it was still too much money. Certainly, the most I have ever spent on non-Apply hardware.
I use opencode (and have a basic Go subscription) and ChatGPT (with a Plus subscription). My goal is to minimize my use of frontier LLMs for private projects. I think now have such a rig.
I run three models on this host (called Colossus):
- Qwen3.8-27B-UD-Q4_K_XL (a dense model with a 64K context)
- Qwen3-Coder-30B-A3B-Instruct-Q4_K_M (a Mixture of Experts model with 128K context)
- gpt-oss-20b-F16 (MoE model with 128K context)
Using the frontier model, benchmarking scripts were created to dial in the settings on these LLMs.
Only one LLM runs at a time, but I have a script that launches llama server with a router. I run that one script and then I can select the model I want to use in OpenCode.
The MoE models (once they are loaded) run very well and have snappy token generation. However, their reasoning is questionable. Their tool use is OK.
The Qwen 3.8 model is slow (about 10 t/s) but accurate. This is my go-to model when I need the LLM to do software engineering and discovery tasks correctly.
Which brings me to this monster flow chart.
I have a game called ProspectBoy 3000. And although a lot of the game works as expected, the architecture went a little pair-shaped in places. I have fixed some of this by hand, but know I constructed an architectural review with Qwen.
This workflow is particularly challenging because there is only one agent in the loop at a time. Therefore, a perl driver is used to launch opencode with instructions that examine only one Perl library file at time. The results are written to disk. The list of modules to examine is also updated.
This review has been going for 16 hours without my intervention. I will likely go for another 48 hours.
Qwen is fantastic. I can work around latency. I can't work around inaccuracy.
When I need interactivity, I have the MoE models which are great too.
Given the insane prices of VRAM, I have to believe 2027 will be the year of local LLMs. The good news is, many workflows already are possible on 64GB machines. 128GB is a luxury as is speed. If you can get it though, take it.
Cheers,